WebTraceAI
Tells you whether a website's design was made by a person or by AI.
- 80%+
- accuracy
- <500ms
- per prediction
- 200+
- screenshots, collected by hand
Dataset, model and training
FastAPI, scikit-learn, OpenCV, React, Vite
What it is
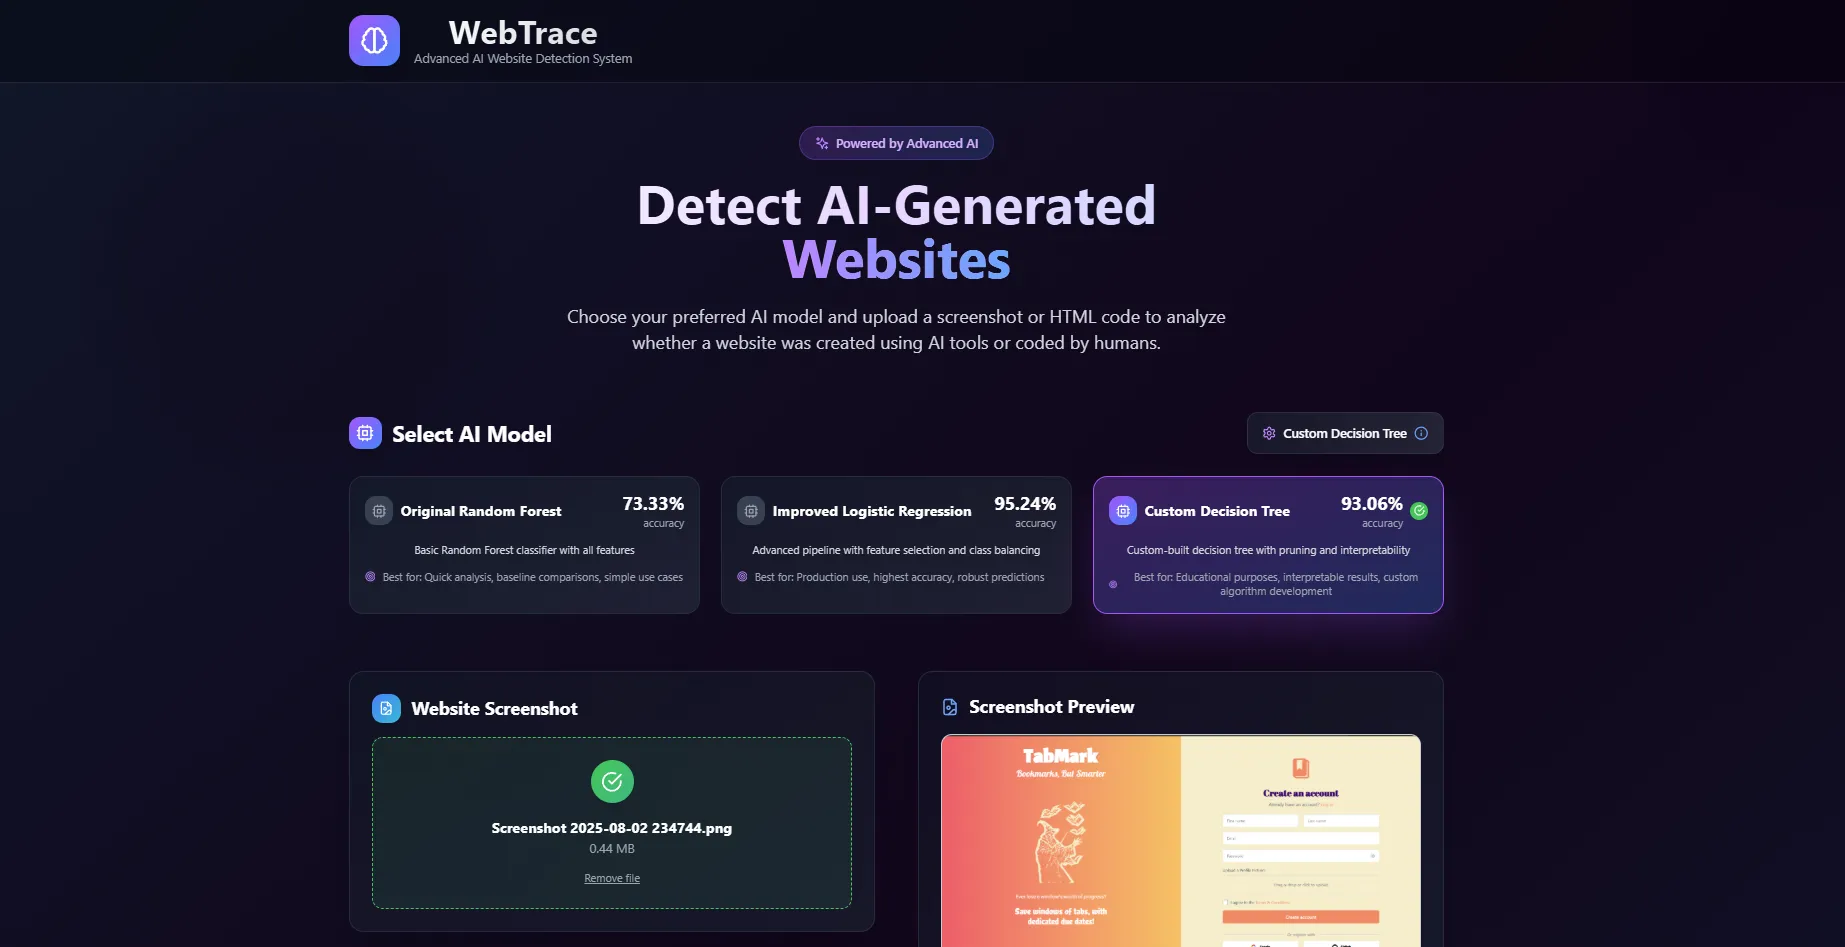
WebTraceAI is an AI detector for web design. Give it a screenshot of a site and it tells you whether a person designed it or an AI generated it.
Why I built it
AI site builders got good fast, and I wanted to know if their output still had a look you could measure.
Architecture
- client
- service
- database or storage
- model
- scheduled job
- bold outline = what I owned
- request
- async: event, message, webhook
- I collected screenshots by hand.
- They became a labeled dataset, split between AI-generated and human-made sites.
- Training pulls visual features out with OpenCV and fits several models, including a random forest and a custom decision tree.
- The best model, the random forest, is loaded by a FastAPI endpoint.
- The web UI sends a screenshot and gets a verdict back.
The interesting part
There wasn't a dataset, so I made one. With only 200+ examples, the features mattered more than the model: the random forest won, getting it right 80%+ of the time and answering in under 500 milliseconds.
Results
- accuracy
- 80%+
- inference
- <500ms
- dataset
- 200+ screenshots
What I'd change
I'd collect a lot more data before trying more models. With 200 screenshots, the dataset was the limit, not the model.